Wenye Yu
Robotics & Embodied AI · Ph.D. Student
Robotics & Embodied AI · Ph.D. Student
I am a second-year Ph.D. student at the Machine Vision and Intelligence Group (MVIG), Shanghai Jiao Tong University, advised by Prof. Cewu Lu. I also work closely with Prof. Chuan Wen.
I received my Bachelor’s degree from the first session of Guozhi Class (held by Prof. Xiaoou Tang), Shanghai Jiao Tong University. Previously, I was a research intern at InternRobotics, supervised by Dr. Jiangmiao Pang.
My research focuses on Robotics and Embodied AI, particularly human-in-the-loop learning and efficient post-training for robotic manipulation.
Preprint · 2026
Value as Memory (VaM) combines value caching with online real-world reinforcement learning for general robot policies. Recent value predictions provide task-progress memory to reduce ambiguity under partial observability, while concurrent data collection and training reuse offline demonstrations, off-policy human interventions, and on-policy rollouts for continued policy improvement.
arXiv · 2026
RoboRSI organizes robot self-improvement around Top-Down Skill Refinement. A multi-agent system plans tasks, executes skills, diagnoses failures, and validates local revisions, accumulating reusable capabilities for long-horizon mobile manipulation under human guidance.
arXiv · 2026
RoboPrompt translates points, sketches, and directional cues into action drafts that existing diffusion and flow-matching policies refine. This lightweight interface supports intuitive failure recovery and collects guided rollouts for further policy improvement.
Research Blog · 2026
Noe-0 brings together data collection, models, and infrastructure for embodied intelligence. It uses non-embodied data throughout pre-training and post-training, combining action learning with implicit world modeling to preserve dexterity and improve transfer.
CoRL 2026 (spotlight)
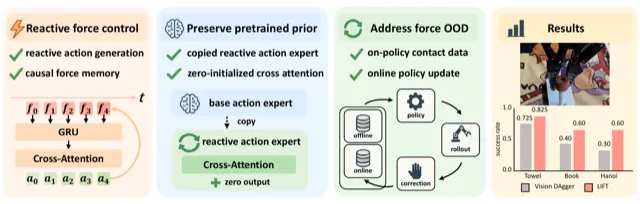
LIFT adds reactive force feedback to pretrained vision-language-action policies while preserving their general manipulation knowledge. By combining causal force memory with online DAgger corrections, it accelerates post-training and improves performance on contact-rich manipulation tasks.
IEEE Robotics and Automation Letters (RA-L) · 2026 · Best Paper Award at IROS 2025 HRII Workshop
ARMADA is a multi-robot deployment and adaptation system with human-in-the-loop shared control, featuring an autonomous online failure detection method named FLOAT. It enables scalable deployment of pretrained policies and thereby expedites policy adaptation to novel scenarios.
arXiv · 2026
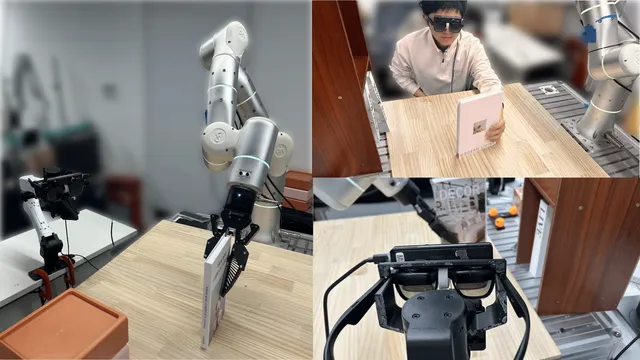
ActiveGlasses is a system for learning robot manipulation from ego-centric human demonstrations with active vision. To enable zero-transfer, we extract object trajectories from demonstrations and use an object-centric point-cloud policy to jointly predict manipulation and head movement.
IEEE/RSJ International Conference on Intelligent Robots and Systems (IROS) · 2025
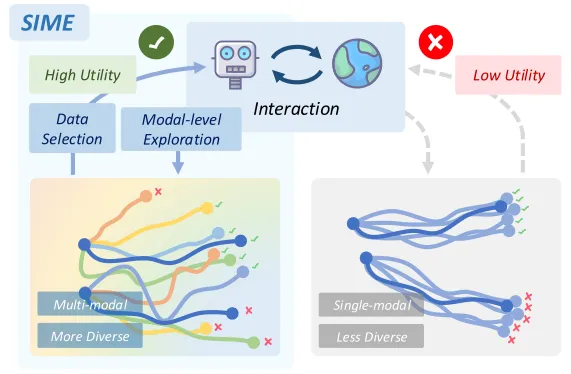
With modal-level exploration, the robot can generate more diverse and multi-modal interaction data. By learning from the most valuable trials and high-quality segments from these interactions, the robot can effectively refine its capabilities through self-improvement.
Robotics: Science and Systems (RSS) · 2025
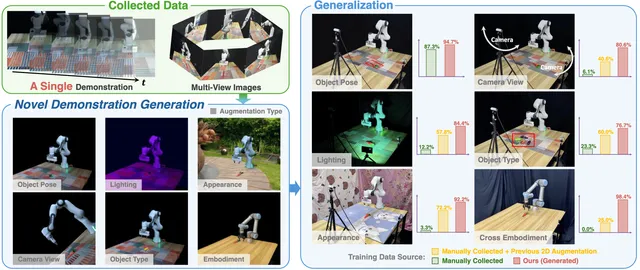
RoboSplat is framework that leverages 3D Gaussian Splatting (3DGS) to generate novel demonstrations for RGB-based policy learning in a one-shot manner, enabling robust performance across six types of visual generalization in the real world.
Conference on Robot Learning (CoRL) · 2024 · Best Poster Award at CoRL 2024 LocoLearn Workshop
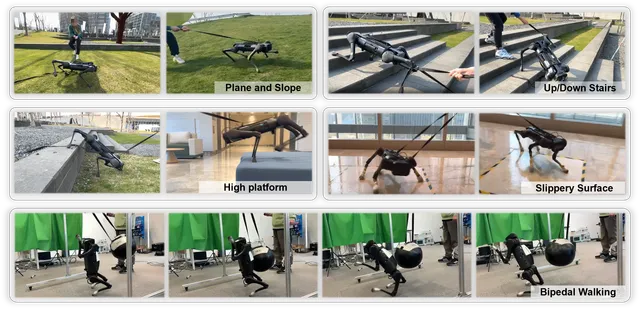
We propose H-Infinity Locomotion Control, an adversarial framework for quadrupedal robots which enhances their robustness against external forces with a performance guarantee.
arXiv · 2024
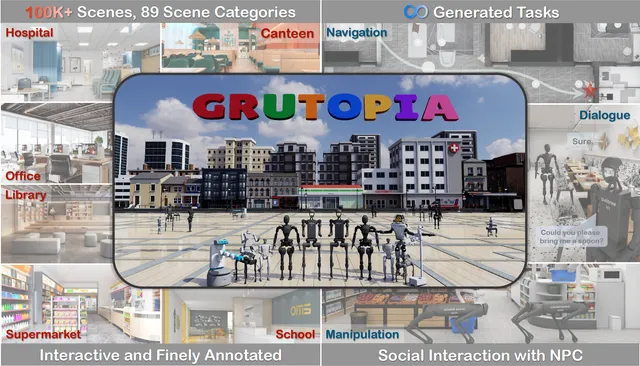
We proposed GRUtopia, the first simulated interactive 3D society designed for various robots. It features (a)GRScenes, a dataset with 100k interactive and finely annotated scenes. (b) GRResidents, a LLM driven NPC system. (c) GRBench, a benchmark posing moderately challenging tasks.
I serve as a reviewer for ICRA 2026.
Outside research, I enjoy music across Hip-Hop, R&B, Rock, Pop, and Electronic. I also follow basketball, tennis, and Formula 1, and enjoy travelling and cinematography.